

TABLE OF CONTENTS
Postgres vs MySQL in 2026: Which Fits Modern Application Workloads Better

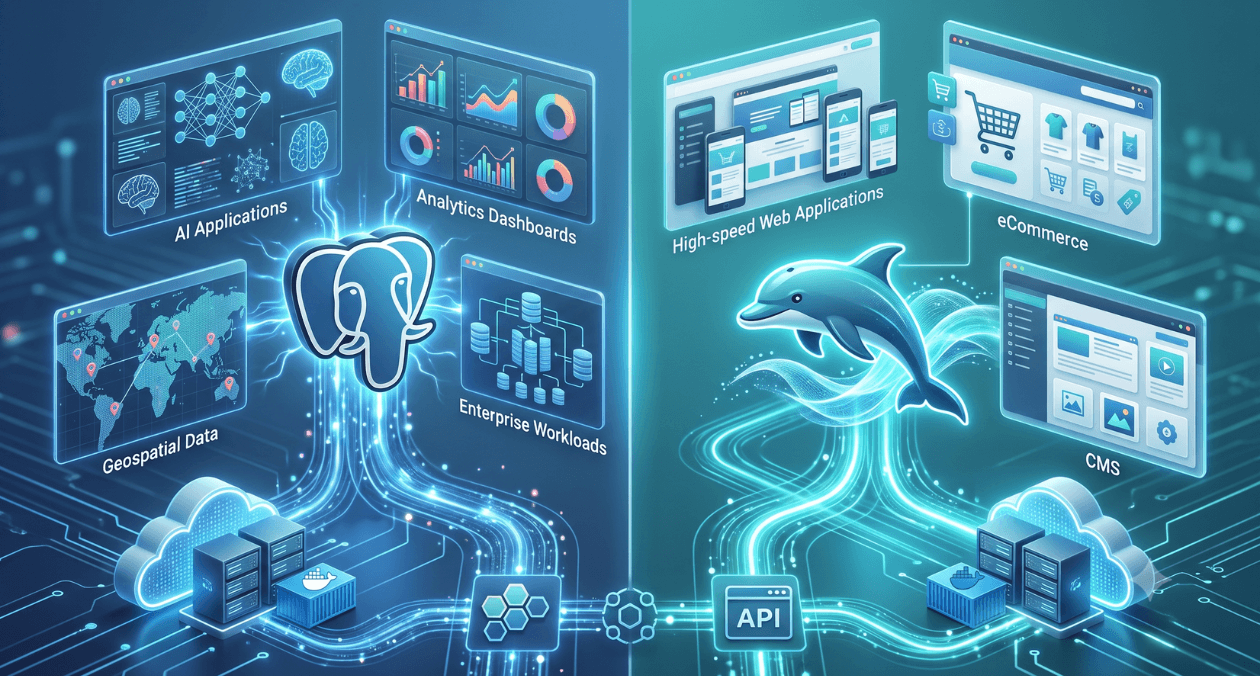
Every couple of years the Postgres versus MySQL debate resurfaces, and 2026 is no different. Teams building new applications still ask the same question during architecture reviews, which database should carry the weight of a growing product. The honest answer is that both engines have matured well past their old reputations, and the decision now comes down to workload shape rather than which one is faster on paper.
Our backend and database teams at Askan Tech get pulled into this conversation almost every time a client starts a new build through our ecommerce development practice, and the pattern is fairly consistent. Teams that spend time with the official PostgreSQL documentation tend to lean Postgres once their queries get complex, while teams running simpler, read heavy applications often stay comfortable on MySQL for longer than expected.
Where MySQL Still Holds Its Ground
MySQL was built with straightforward read and write operations in mind, and it still does that job efficiently. For content heavy sites, simple SaaS tools, and applications where most queries are basic lookups by primary key, MySQL keeps things predictable. Its replication setup is simpler to reason about for small teams, and the operational tooling around it is mature enough that most hosting providers support it without extra configuration. If your schema is not going to change shape often and your queries stay simple, MySQL is rarely the wrong starting point.
Where Postgres Pulls Ahead
Postgres has closed most of the historical performance gap and now leads in areas MySQL was never designed for. Its query planner handles complex joins and window functions with more consistency, and features like partial indexes, common table expressions, and native support for arrays give backend teams options that would otherwise need workarounds. Applications with reporting layers, analytics dashboards, or workflows that need strict transactional guarantees across many related tables tend to be easier to build and maintain on Postgres.
JSON and Semi-Structured Data
This is one area where the two engines have genuinely diverged. Postgres treats JSONB as a first class citizen, letting teams index individual keys inside a JSON document and query it almost as fast as a normal column. MySQL added JSON support years ago too, but indexing inside JSON columns still needs generated columns as a workaround, which adds schema overhead. For products that store flexible attributes, like configurable product catalogues or user preference blobs, Postgres usually needs less engineering effort to keep those queries fast.
Need Help Picking Your Stack
Replication and Failover Behaviour
MySQL’s replication is simple to set up for a single primary with a few read replicas, which is exactly what most small to mid sized applications need. Postgres replication takes a little more configuration up front, but tools built around logical replication give teams finer control over what gets replicated and where, which matters once you are running services across regions or need selective data sync between environments.
| Aspect | PostgreSQL | MySQL |
| Complex queries and joins | Strong, mature planner | Adequate, simpler queries preferred |
| JSON and flexible schemas | Native JSONB indexing | Needs generated columns |
| Replication setup | More configuration, more control | Simple, quick to set up |
| Read heavy simple apps | Good, sometimes more than needed | Very efficient |
Making the Call for Your Application
The right choice rarely comes down to benchmarks alone. A team running a straightforward storefront or content site can be perfectly served by MySQL for years. A team building anything with layered reporting, complex product relationships, or a data model that will keep evolving usually finds Postgres saves engineering time down the road. Platforms built for growing merchants, such as Zyfoo’s commerce stack, often make this call early in their architecture so the database never becomes the bottleneck as order volumes climb. Whichever engine your team picks, the decision should sit close to your actual query patterns and not just the reputation the database carries from a few years ago.
Most popular pages
-
Image Optimization for Web Performance: Formats and Compression
Ask a developer why a page feels slow, and the honest answer is often sitting right in the middle of it. A single unoptimised...
-
Monolith vs Microservices: Choosing the Right Architecture for Your Team
Microservices have dominated architecture conversations for years, to the point where choosing a monolith can feel like admitting you're behind the times. In practice,...
-
Magento Performance Tuning: Caching Layers Explained
Magento has a reputation for being resource-heavy, and while some of that is inherent to running a full-featured enterprise commerce platform, a large share...
Image Optimization for Web Performance: Formats and Compression
Ask a developer why a page feels slow, and the honest answer is often sitting right in the middle of it. A single unoptimised...
Monolith vs Microservices: Choosing the Right Architecture for Your Team
Microservices have dominated architecture conversations for years, to the point where choosing a monolith can feel like admitting you're behind the times. In practice,...
Magento Performance Tuning: Caching Layers Explained
Magento has a reputation for being resource-heavy, and while some of that is inherent to running a full-featured enterprise commerce platform, a large share...